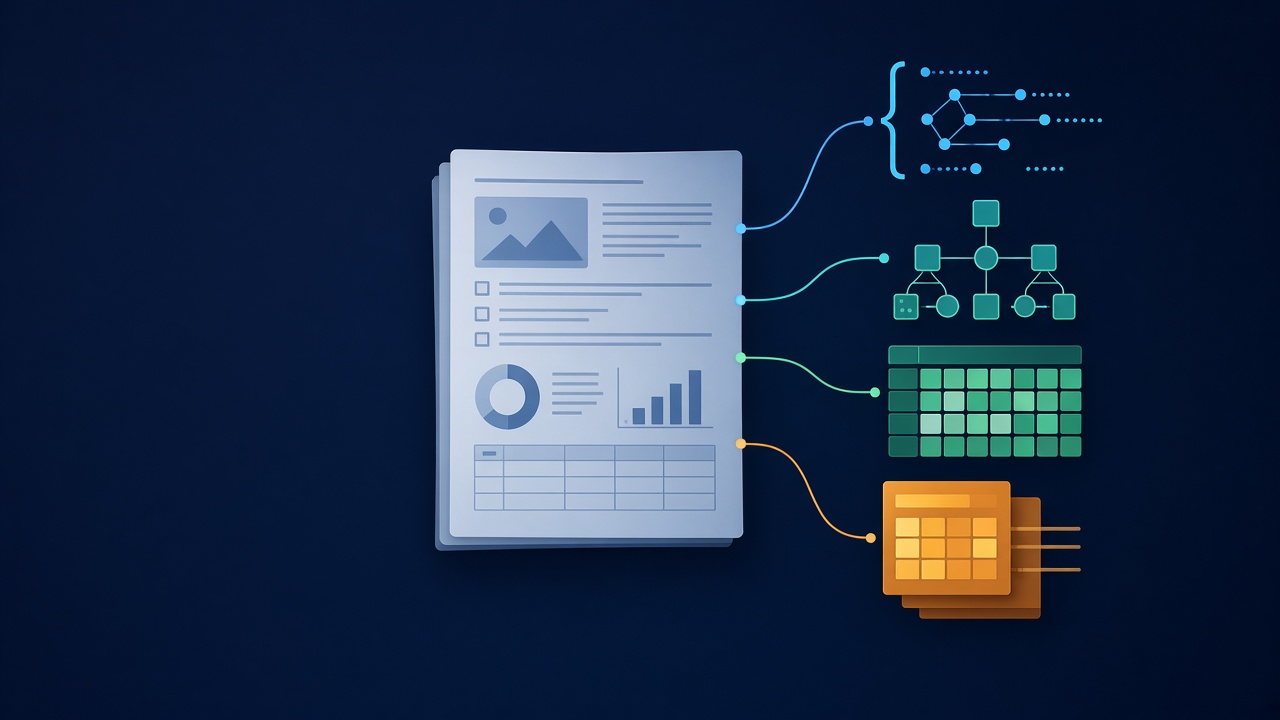
Choosing an OCR output format is not only a technical detail. It affects how easily extracted data can be reviewed, validated, transferred, and loaded into another system. ConvertToData supports JSON, XML, CSV, and XLSX, and each format is useful for a different kind of workflow.
JSON: the default choice for modern applications
JSON represents data as objects and arrays. It is compact, readable, and supported by virtually every current programming language. Nested structures make it suitable for documents that contain both header fields and repeating rows.
Choose JSON when:
- you are integrating through an API;
- the document contains line items or nested sections;
- the result will be processed by JavaScript, Python, PHP, Java, .NET, or an automation platform;
- you need to preserve numbers, Boolean values, arrays, and field relationships.
JSON is usually the best starting point for custom software and automated document pipelines.
XML: a strong fit for established enterprise systems
XML uses tags to describe a structured document. It is more verbose than JSON, but it offers mature validation and transformation standards. Many ERP, EDI, banking, and government systems still use XML as their primary interchange format.
Choose XML when:
- the receiving system requires an XML schema;
- your integration relies on XPath, XSLT, or XML signatures;
- you exchange documents with a legacy or enterprise platform;
- strict schema validation is part of the process.
Do not select XML merely because it looks formal. Use it when the destination ecosystem already benefits from XML tooling.
CSV: simple tabular exchange
CSV stores rows and columns as plain text. It is easy to generate, compact, and accepted by databases, reporting tools, and spreadsheet applications. Its simplicity is also its main limitation: CSV does not naturally represent nested objects or several related tables.
Choose CSV when:
- the useful result is a single flat table;
- you need a lightweight import into a database or analytics tool;
- files will be processed in batches;
- the receiving system has a stable column specification.
Define the delimiter, character encoding, quoting rules, decimal separator, and date format before exchanging CSV files. These details prevent common import errors.
XLSX: convenient for people and business review
XLSX is the native workbook format used by Microsoft Excel and many compatible applications. It is easy for business users to open, filter, annotate, and correct. It also supports multiple sheets and typed cells.
Choose XLSX when:
- a person will review or edit the extracted data;
- the result is part of a finance or operations workflow;
- you need separate worksheets for different tables;
- the next step is analysis in a spreadsheet.
XLSX is less convenient for service-to-service APIs because it is a binary package and requires a workbook library to process safely.
Quick decision guide
- Application or API integration: JSON.
- Enterprise schema or legacy integration: XML.
- Flat database import or batch analytics: CSV.
- Human review and spreadsheet work: XLSX.
Plan for data types and validation
No format eliminates the need for a data contract. Decide which fields are required, whether amounts are numbers or formatted strings, how missing values are represented, and which date and currency formats are accepted. Validate extracted results before importing them into production systems.
It is also useful to preserve the original file name and a processing identifier. They provide traceability when a result needs to be reviewed or converted again.
Test with real documents
The best format is the one that reduces work in the next step. Convert the same representative document into several formats and test each result with the actual destination system. You can compare supported outputs on the online converter and automate the selected format with the ConvertToData API.