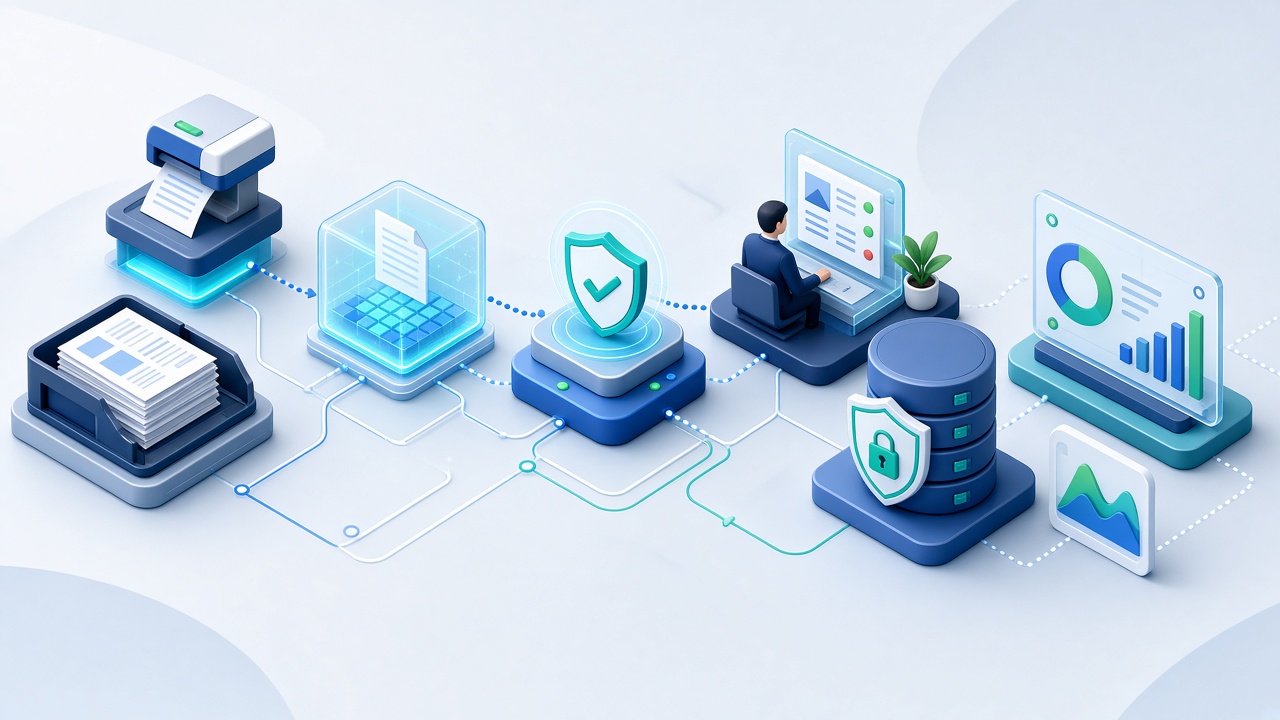
A successful OCR demonstration can read a document. A reliable document data extraction workflow must do much more: accept files consistently, produce structured output, detect errors, protect sensitive information, and recover when an external system is unavailable.
The following design works for invoices, orders, reports, statements, and many other business documents.
1. Define the business outcome
Start with the destination, not the OCR engine. Identify which fields the business process needs and where each value will go. A workflow that creates an invoice in an accounting system has different requirements from one that prepares a searchable analytics dataset.
Document the required fields, optional fields, allowed values, and validation rules. This becomes the data contract used by developers, operators, and reviewers.
2. Standardize document intake
Files may arrive through an upload form, email inbox, shared folder, mobile application, or API. Normalize these channels into one intake stage. Assign every submission a unique processing ID and retain basic metadata such as source, arrival time, original file name, and document type.
Reject unsupported or unexpectedly large files early. If files are retrieved from URLs, allow only trusted protocols and apply network security controls to prevent access to internal resources.
3. Check input quality
Before conversion, detect obvious quality problems:
- missing or blank pages;
- images that are too small to read;
- rotated or severely skewed scans;
- password-protected documents;
- duplicate submissions;
- documents in an unexpected language.
Some issues can be corrected automatically. Others should be returned to the sender with a clear explanation.
4. Convert to a structured format
Select an output format based on the next system. JSON is well suited to APIs and nested records, XML to schema-driven enterprise integrations, CSV to flat imports, and XLSX to human review. ConvertToData supports all four formats.
For automated workloads, send conversion requests through the API. Keep the API key in a secrets manager or environment variable, use HTTPS, set sensible connection and response timeouts, and never log credentials.
5. Validate structure and business rules
Separate technical validation from business validation. Technical checks confirm that the response can be parsed and contains the expected fields. Business checks confirm that values make sense.
Typical business rules include:
- required identifiers are present;
- amounts and quantities are valid numbers;
- totals reconcile with line items and tax;
- dates fall within an acceptable range;
- codes match known customers, suppliers, products, or currencies;
- the same document has not already been processed.
Do not turn a missing value into a zero unless the data contract explicitly defines that behavior. Missing, unreadable, and genuinely zero are different states.
6. Design an exception queue
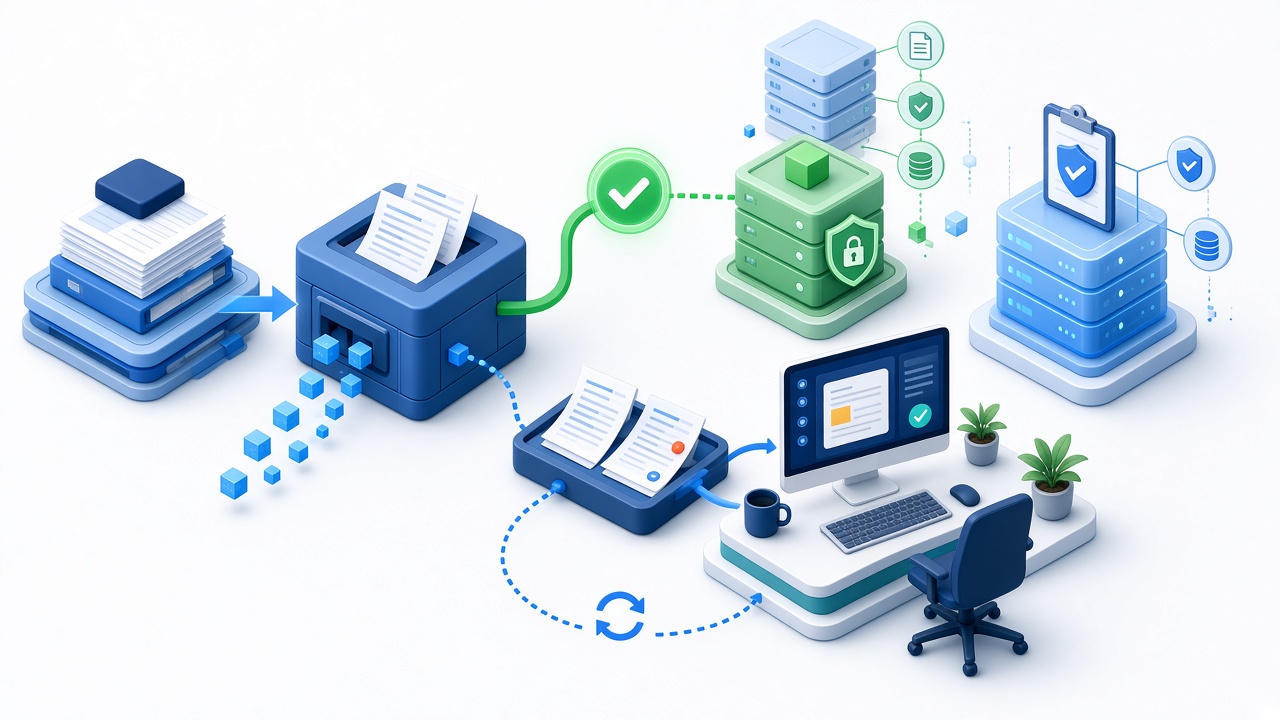
Not every document should flow straight through. Create a review queue for results that fail validation or contain uncertain values. Show the original document beside the extracted fields and explain which rule failed. A reviewer should be able to correct the data and resume processing without starting again.
Track correction patterns. Repeated failures from one supplier or template may indicate a source-quality issue or a validation rule that needs adjustment.
7. Make retries safe
Networks and destination systems occasionally fail. Use retry policies for temporary errors, but avoid retrying invalid requests indefinitely. Exponential backoff reduces load during an outage.
Make downstream operations idempotent: processing the same job twice should not create duplicate invoices or records. A stable processing ID or document fingerprint can be used as an idempotency key.
8. Protect documents and credentials
Business documents may contain personal, financial, or commercially sensitive information. Apply least-privilege access, encrypt traffic, restrict logs, and define how long source files and extracted results are retained. Do not place API keys, full document contents, or sensitive field values in routine application logs.
Review the security controls of every storage and integration step, not only the conversion request.
9. Monitor workflow health
Useful operational metrics include processing volume, conversion duration, validation failure rate, retry count, exception-queue age, and downstream delivery failures. Alert on sustained changes rather than a single difficult document.
Keep audit events that connect the intake record, conversion response, reviewer corrections, and final destination record. This makes support and compliance investigations much faster.
Start small and expand deliberately
Begin with one document type and a representative sample from real sources. Measure extraction quality and review effort, then refine the data contract and validation rules. Once the exception rate is manageable, add more sources or document types.
You can test document conversion on the ConvertToData website. When the workflow is ready to automate, use the developer area and current API documentation.